Resume parsing extracts information from a CV or resume into structured fields: a person’s job titles, employers, dates, education and other details. It turns a document into data a recruiting team can review and use. It does not verify the person’s claims, decide whether they meet a brief or establish that two records belong to the same person.
Imagine a CV that lists an interim appointment beside a permanent role. Both entries are readable, but the relationship between them matters. A parser may identify the words correctly and still attach the wrong dates to the wrong job. The useful question is what reaches the candidate record after review, not how convincing the extracted text looks.
How resume parsing works
- Read the document. The system needs usable text. A text-based PDF differs from a scanned page; an image may require optical character recognition. Whether a particular file is supported depends on the tool.
- Identify sections and entries. Work experience, education and contact details need to be separated. Columns, repeated headings and page breaks can disrupt the reading order.
- Assign information to fields. A title, employer and date range must belong to the right experience entry. Recognising a date is different from knowing which role it describes.
- Present a structured result. The output may be a candidate record or another structured format. Check the actual destination rather than assuming an API or export is included.
- Review before use. Compare the fields with the document, resolve ambiguity and keep the original available for later checks.
These are the tasks involved in extraction, not a claim that every parser uses the same technology. A product may combine document reading, rules and language models. The implementation label does not tell you whether it handles your CVs correctly.
A fictional CV snippet, field by field
Fictional example: document CV-EX01 says “Acting Operations Lead — Division A”, “03/04/2022–present” and “Project Lead, Division B — 2020–2022”. It lists an engineering degree but no email address. The following table shows what a reviewer should check; it is not output generated by Yena.
On a small screen, scroll the table horizontally. Keyboard users can focus the table region and use the arrow keys.
| Source information | Structured field | Human check |
|---|---|---|
| Acting Operations Lead | Current job title | Keep “Acting”. Removing it changes the meaning of the appointment. |
| 03/04/2022–present | Current role start and end | Confirm whether the date means 3 April or March 4. Do not silently choose a convention. |
| Project Lead, Division B — 2020–2022 | Previous experience entry | Keep the employer and dates attached to this role, not the current one. Do not invent missing months. |
| Engineering degree; no email | Education; email | Record the qualification as stated. Leave email absent rather than deriving an address. |
A blank field can be the correct result when the document contains no answer. An apparently complete record can be worse if it fills gaps with assumptions. Distinguish missing source information from information that was present but not extracted.
Parsing, matching, ranking and identity are separate checks
Parsing answers “What does the document say?”. Candidate matching asks how a profile relates to a role’s criteria. Ranking orders profiles under a particular method. Duplicate detection asks whether two records concern one person. None of these steps independently confirms employment, qualifications, willingness to move or suitability for a client.
For example, a CV mentioning a finance transformation does not prove the person led it. Extraction can preserve that statement; a recruiter still needs to understand the responsibility and evidence. Similarly, a matching email address is an identity signal, not a reason to overwrite every field. Our guide to duplicate candidate detection covers that separate decision.
What to check in Yena’s CV import workflow
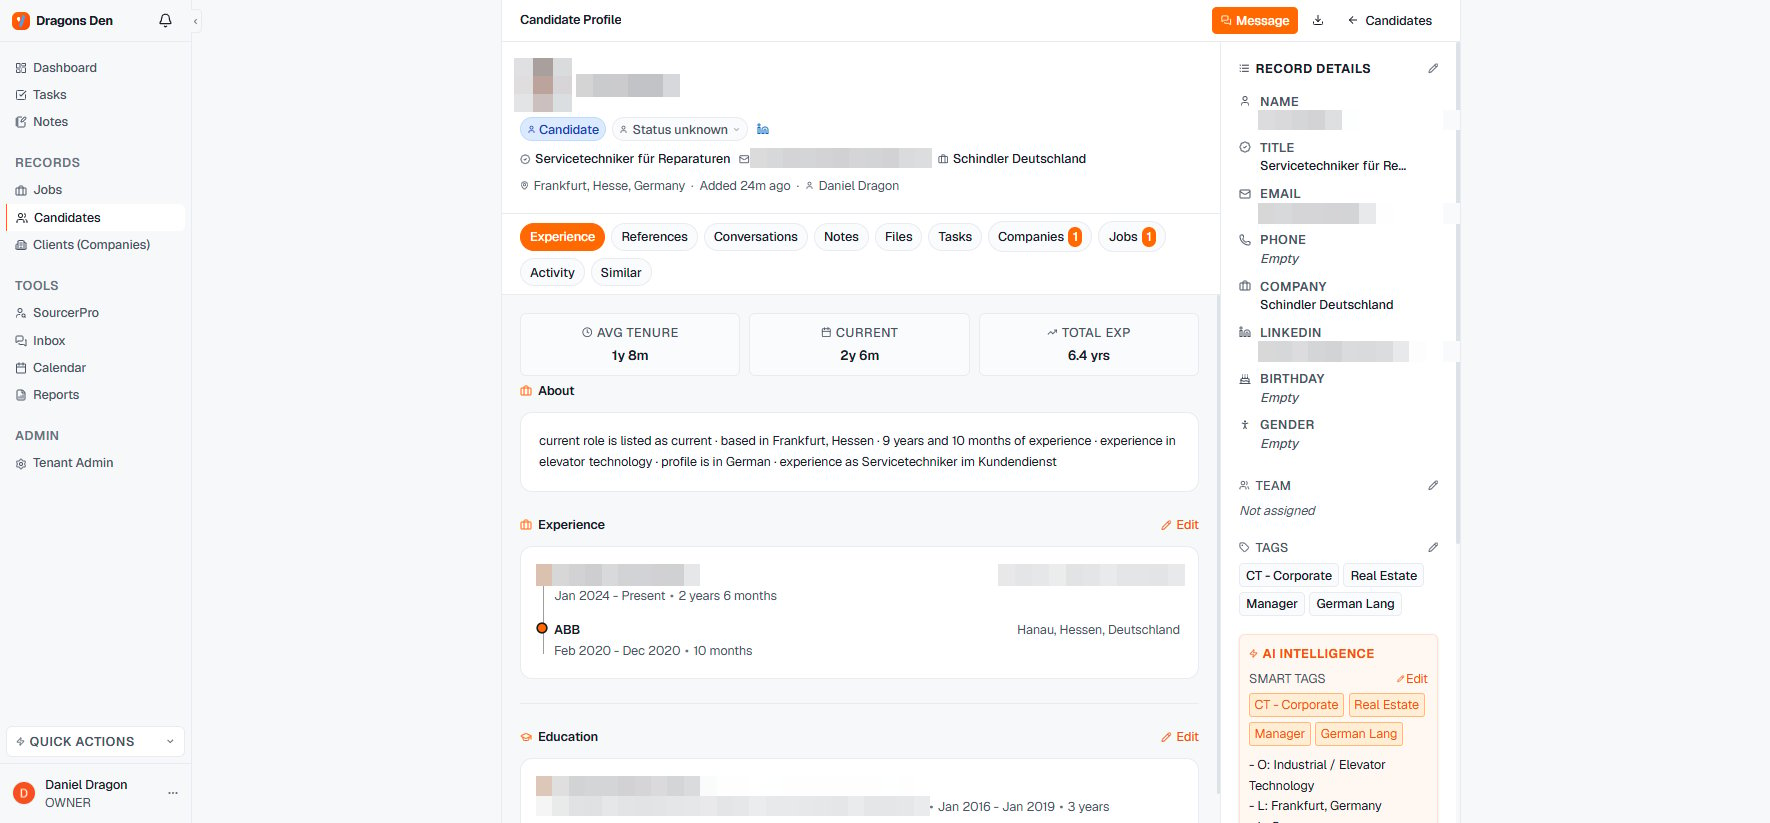
The official Import CV guide places the action in Candidates and in a job’s pipeline pool. It describes extracting name, title, contact details, experience and education, reviewing the result before saving, and attaching the original document under Files.
The same guide says a CV import fills empty fields rather than replacing existing populated values. That protects earlier entries under the documented rule; it also means an old incorrect value may still need deliberate correction. Check the existing record as well as the new document.
Confirm accepted files and current upload limits in your workspace before preparing a larger upload. Agree the scope of a historical ATS import separately, including which conversations, tasks and application records need to be transferred and checked.
Evaluate the result with a representative sample
Select documents you are entitled to process and that reflect the work: different layouts, languages, scans and overlapping roles. Write the expected fields before testing. Mark each result as correct, wrong, missing despite being stated, or correctly absent. Keep a separate note for unsupported files.
Review relationships between fields, not just isolated words. The right employer attached to the wrong role is an error. Decide which errors block saving or downstream use and record the correction work required. An overall accuracy percentage without a field definition and sample description tells a buyer little.
After saving a test record, confirm that another authorised colleague can find the relevant information and open the source file. Then evaluate role criteria separately. A parser test demonstrates extraction on that sample; it does not demonstrate hiring quality.
Some of our customers
Try it with your team
Check the role criteria after checking the record
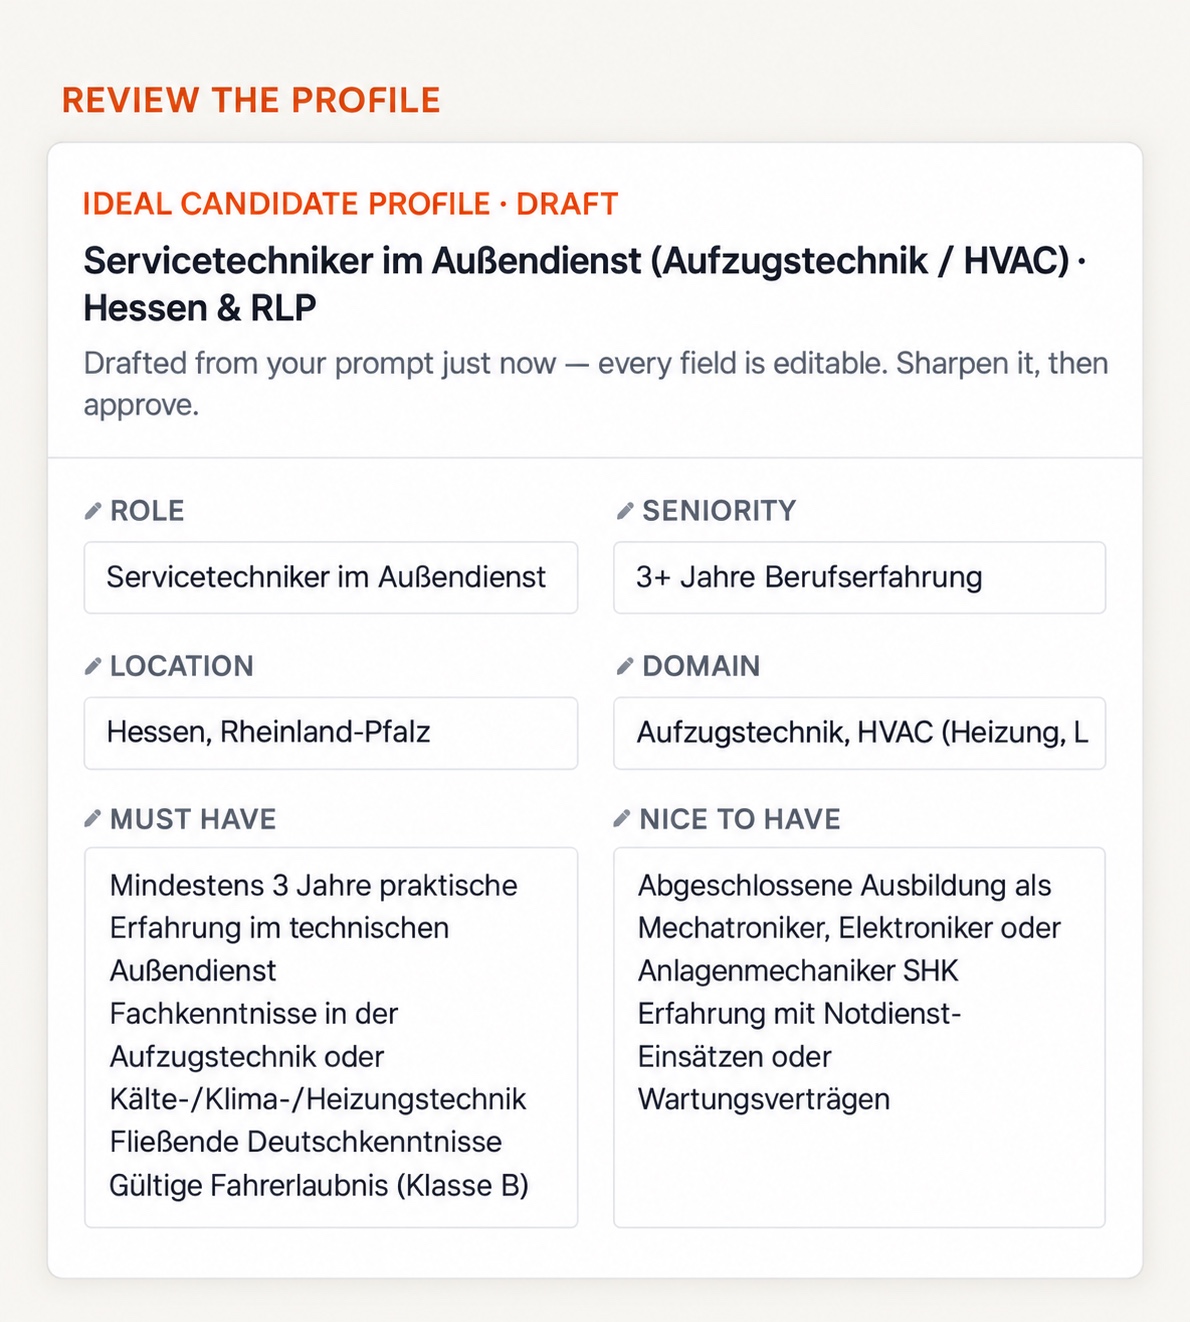
This view shows preparation of a search profile in Yena. It is a separate workflow from CV import and does not show a parser accuracy result.
- Choose a real mandate and specify its essential requirements.
- Review the proposed search profile before running a search.
- Inspect the shortlist and record which requirements need more evidence.
Sources checked on 14 November 2026
Product workflow statements use the official CV import guide, candidate record guide and data migration guide. The fictional example and evaluation checklist are editorial guidance, not measured product results.
Frequently asked questions
What is resume parsing?
Resume parsing extracts information from a CV or resume into structured fields, such as job titles, employers, dates and education. A recruiter checks those fields against the source document before relying on them. Extraction does not establish that a claim is true or that the person fits a role.
Is resume parsing the same as candidate matching?
No. Parsing structures information from a document. Matching compares a candidate with a role’s requirements. Ranking orders results according to a method, and identity matching checks whether records concern the same person. Each task needs its own evidence and review.
How should I test a resume parser?
Use a representative sample you are entitled to process, including the layouts and languages you receive. Write down the expected fields, compare the extracted results with the documents and record omissions, wrong values and wrongly attached facts. Check how review, saving, existing records and original files work before wider use.